
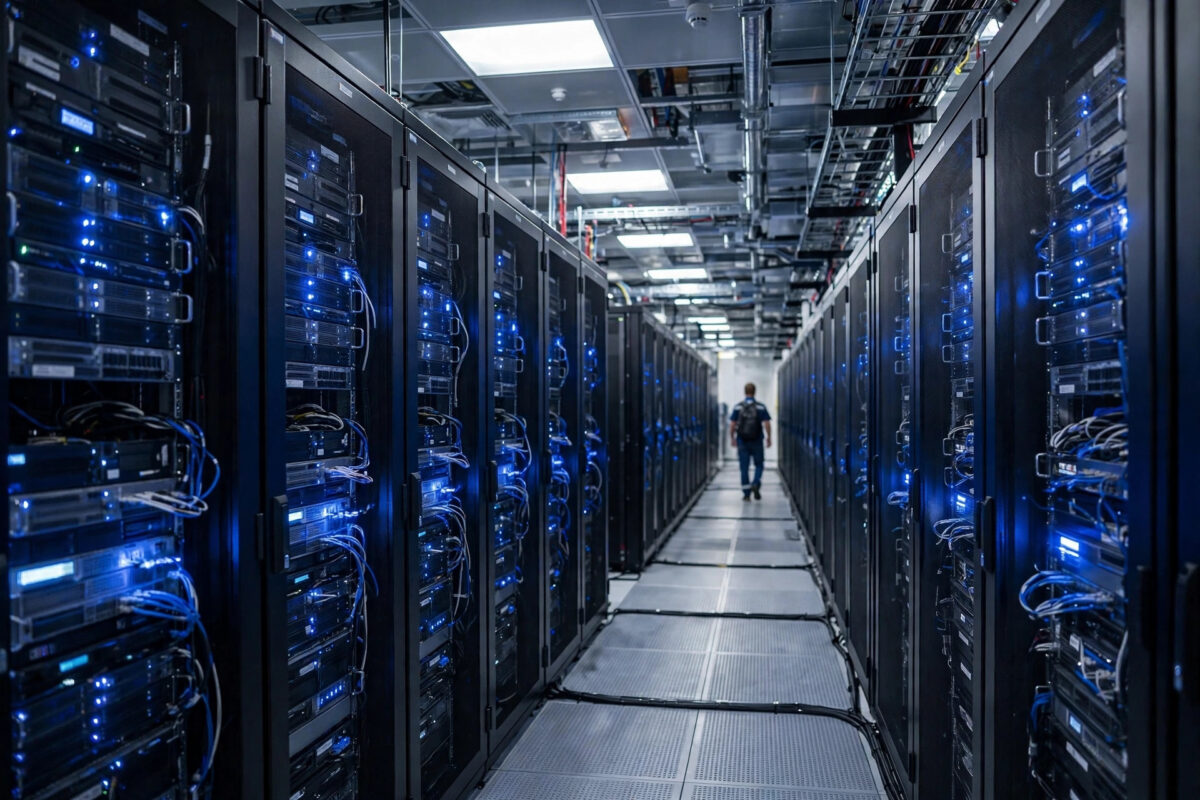
On the morning of Monday 20 October 2026, a remarkable slice of British daily life stopped working. Banking apps would not open, parcels could not be tracked, and major websites sat frozen. The common thread was one place most people have never thought about: a Google Cloud data centre region in the UK, and a power problem inside it.
This explainer walks through what happened, why a single incident hit so many unrelated services at once, and what it tells us about how the modern internet is actually built.
Quick Answer
The outage was caused by a power event at Google Cloud’s europe-west2 region, which serves the UK. When power and the systems depending on it failed, the banks and services hosted there — including Revolut, Lloyds, Halifax, DPD, Rightmove and Royal Mail services — lost the servers their apps and websites run on, so they failed together until power and systems were restored and services recovered in stages.
What Is a Cloud Region, and Why Does It Matter?
Companies no longer keep their computers in a cupboard at head office. They rent computing from cloud providers — Google Cloud, Amazon’s AWS, Microsoft Azure — which run enormous data centres. A “region” is one of those clusters in a geographic area, in this case europe-west2, located in the UK.
Banks choose a UK region deliberately: keeping data in-country helps with regulation, and closeness keeps apps fast. The trade-off is concentration. When dozens of important services share one region, that region becomes a single point whose bad morning becomes everyone’s bad morning.
Inside the apps themselves nothing was broken. A banking app is mostly a window: the balances, payments and logins happen on servers. When those servers lose power or become unreachable, the window shows an error no matter how perfect the app is. This is the same pattern described in our guide on how to check Google Cloud service status when websites will not load, which shows you how to watch these incidents yourself next time.
What Actually Happened on 20 October
Google Cloud reported a power event affecting the europe-west2 region during the morning. In data centre language, a power event means the electricity supply or distribution inside the facility failed in a way that backup systems could not fully cover or that forced equipment to shut down for safety.
Modern data centres are built with layers of backup — batteries, generators, redundant feeds — so a visible outage of this scale usually means something more than a simple flicker: a failure serious enough to take equipment offline and require careful, staged restoration. Turning a data centre back on is not like rebooting a laptop; systems must return in the right order, with databases and networks verified as they come up, which is why recovery took hours rather than minutes and arrived service by service.
As the region failed, the customer-facing damage spread across Britain. Banking apps from Revolut, Lloyds and Halifax rejected logins and payments. DPD tracking went down. Rightmove and Royal Mail services faltered. Outage trackers recorded enormous simultaneous spikes, and the incident led UK tech news through the day. Google Cloud’s own status dashboard carried the incident as engineers worked through it.
Why Did So Many Different Services Fail Together?
Three structural reasons explain the pile-up. First, shared hosting: competitors often rent from the same provider in the same region, so a regional failure does not respect brand boundaries. Your two “separate” bank accounts may be neighbours in the same building.
Second, shared dependencies: even services not hosted in europe-west2 may call upon smaller components that are — a payments processor, a maps service, an identity checker. When a dependency fails, the service built on it degrades in ways its own status page struggles to explain.
Third, failover limits. Well-built services can shift traffic to another region, but banking is cautious work: data residency rules, consistency requirements, and the sheer risk of switching mid-incident mean many financial systems are designed to pause rather than fail over automatically. A paused bank is embarrassing; a bank that loses track of money mid-switch is a catastrophe, so the industry chooses embarrassment.
What Happened to People’s Money and Data?
The reassuring answer is: essentially nothing. Outages of access are not losses of records. Account balances and transaction histories are stored redundantly, and the incident affected the ability to reach and process them, not their existence. Payments attempted at the worst moments were the main area needing care, with banks advising customers to check statuses before retrying to avoid duplicates — the same advice we give in our guide on why the Revolut app is showing Something Went Wrong today.
Google’s post-incident process typically includes a published review of the cause and the fixes, and affected providers run their own reconciliations. If you ever do find a genuine error after an outage — a duplicated payment, a missing transfer — banks have established processes to correct them once you report the details.
Lessons From One Bad Morning
For the industry, the lesson is about concentration risk. A handful of cloud providers now underpin a startling share of daily life, and regulators have been increasing their scrutiny of exactly this scenario. Expect more pressure for tested multi-region designs, especially in finance.
For the rest of us, the lessons are smaller and practical. Keep a second way to pay. Know that when five apps fail together, the problem is almost certainly not you. And learn where the status pages live, because the next incident — whatever causes it — will reward the people who can tell an outage from an account problem in the first five minutes.
What Google and the Banks Do Next
Incidents of this scale trigger a formal aftermath. Google will publish a post-incident review examining the power failure, why backups did not fully absorb it, and what engineering changes follow. The affected banks and services run their own reviews in parallel, reconciling every payment attempted during the window and reporting to regulators where required. Some of that output is public; much of the value is in the fixes nobody ever hears about.
Common Mistakes to Avoid
- Blaming the app and reinstalling everything. The apps were fine; their servers were unreachable.
- Assuming money vanished. Access failures do not erase balances or records.
- Retrying payments blindly during recovery. Check statuses first to avoid duplicates.
- Trusting outage-day messages from “your bank.” Scammers exploit these incidents within hours. Use official apps and sites only.
- Thinking it cannot happen again. Shared infrastructure means shared fate; a backup payment method is permanent wisdom, not paranoia.
Conclusion
A power event in one Google Cloud region silenced a crowd of UK services because modern apps are windows onto shared servers, and those servers shared a building, a power supply, and a bad morning. Nobody’s money disappeared; access did. The fix for users is not technical at all — it is a spare card, a calm head, and knowing an outage when you see one.
Frequently Asked Questions
Was the outage a cyberattack?
There is no indication of that. Google Cloud attributed the incident to a power event at the region, and the pattern — one region, many unrelated customers, staged recovery — matches infrastructure failure, not an attack.
Why did some apps keep working while others failed?
Services differ in where they are hosted and what they depend on. Apps hosted in other regions or on other providers were untouched, and even within the affected region, some systems had better failover than others.
How long did the disruption last?
The worst of it ran through the morning of 20 October 2026, with services recovering in stages over several hours as power and systems were restored and verified.
Can banks prevent this happening again?
They can reduce the risk with multi-region designs and tested failover, but banking rules and data safety make instant switching genuinely hard. The realistic goal is rarer, shorter incidents, not the total abolition of outages.
Where can I read the official explanation?
Google Cloud publishes incident details on its status dashboard and typically follows major events with a fuller post-incident review. Affected banks also post summaries for their customers.
[…] This is why the tracking page can look alarming in several distinct ways during an outage. It may fail to load at all. It may load but show your parcel stuck at a scan from hours ago. Or it may show a delivery estimate that slides quietly into the past. All three mean “we cannot currently tell you,” and none of them mean “your parcel has vanished.” The general outage picture behind days like this is explained in our article on what caused the Google Cloud outage that took UK banking apps offline. […]
[…] detailed explainer on what caused the Google Cloud outage that took UK banking apps offline walks through that specific incident step by step; this article is about the general pattern it […]